Linguistic Context and Raw Data in Simulated Bitcoin Backtests
LLMs already have web search, RAG, and document ingestion. The question is not whether external context helps. The question is whether pre-analyzed, linguistically structured context outperforms raw information access. We tested this directly.
Key Findings
- -In these simulated Bitcoin runs, the agent with structured briefings ended ahead of the agent given prices only.
- -Briefings arm against the price only arm: +4.46 to +15.97 points across the 7 runs
- -Run 2 used Sonnet 4.5 and the other runs Opus 4.6; the briefings arm ended ahead of the price only arm in each.
01 Introduction
The conventional approach to giving LLMs real-time information is straightforward: connect them to data. Web search, API calls, document retrieval, CSV ingestion. The model gets the numbers, the model reasons about the numbers. This is how most RAG pipelines work, and it is how most financial AI integrations are built. Feed the model a JSON payload of price data, on-chain metrics, and macro indicators. Let it figure out what they mean.
PreReason started from a different premise. LLMs are language processors, not data parsers. They were trained on structured prose, not on spreadsheets. When a model receives a JSON array of 200-day moving average values, it has to first interpret what those numbers represent, then reason about what they imply. That interpretation step is lossy. When the same model receives a pre-computed analysis stating that BTC is 31% below its 200-day moving average (a widely-watched price trend indicator) with decelerating downward momentum and a hash ribbon (a mining health signal derived from hash rate trends) capitulation signal active for 46 days, it can reason about those signals directly. The computation happened upstream. The model does what it was trained to do: process language.
LLMs cannot reliably perform internal mathematical calculations. Ask a model to compute a moving average from raw price data and the result will be unreliable. Give it a pre-computed moving average with a trend label, and it can reason about that signal accurately. PreReason briefings do the math upstream. The model receives computed results it can reason about.
The question we needed to answer was not "does context help?" Of course it does. Anyone who has pasted an article into a chat window knows that. The question was whether the form of the context matters. Does pre-analyzed, linguistically structured financial context produce better decisions than raw real-time information access?
We tested this across 7 simulated backtest runs over one Bitcoin window, September 2025 through March 2026, revising the briefings between runs. Every tick falls after Opus 4.6's training data cutoff (August 2025). The model has zero learned knowledge of the market events it is trading. Every run compared a Treatment arm (receiving PreReason briefings) against a Control arm (price only) and a Placebo arm (stale briefings). The final two runs added a Control-WS arm with live web search, testing raw information access directly.
All 7 runs produced a positive delta for Treatment over Control, ranging from +4.46pp to +15.97pp (pp = percentage points, the absolute difference between two percentages). More telling: Treatment outperformed Control-WS (web search) by +2.24pp in Run 6 and +9.38pp in Run 7. The model with structured briefings beat the model with full internet access.
These 7 runs represent the production-quality experiments that emerged from an iterative development process. Earlier iterations used different fee structures, preamble designs, and briefing architectures. Some produced no measurable delta. One produced a negative delta that led to a preamble redesign (the distinction between universal constraints and encoded strategy, described in Section 04). The failures shaped the architecture. The 7 runs presented here share consistent methodology: synchronized tick execution, 0.045% fee structure ( Runs 1 and 2 used 0.1%), complete audit trails, and the same core preamble. Each run either introduced a configuration change or served as a deliberate replication ( Run 5 replicates Run 4 with no changes). No configuration was run repeatedly with only the best result kept.| Run | Name | Window | Ticks | Arms | Treatment | Control | T vs C | BTC |
|---|---|---|---|---|---|---|---|---|
| 1 | First Run | Sep 1 - Nov 30, 2025 | 91 | 3 | -3.16% | -8.44% | +5.28pp | -16.1% |
| 2 | Second Model | Sep 1 - Nov 22, 2025 | 83 | 3 | -2.03% | -6.49% | +4.46pp | -21.4% |
| 3 | Briefing Restructuring | Sep 1, 2025 - Feb 28, 2026 | 181 | 3 | -10.35% | -15.69% | +5.34pp | -39.2% |
| 4 | Four Briefing Set | Sep 1, 2025 - Mar 4, 2026 | 185 | 3 | +0.21% | -14.69% | +14.90pp | -37.5% |
| 5 | Run 4 Repeated | Sep 1, 2025 - Mar 6, 2026 | 187 | 3 | +8.46% | -6.31% | +14.77pp | -34.3% |
| 6 | First 4-Arm Run | Sep 1, 2025 - Mar 6, 2026 | 187 | 4 | +3.18% | -9.51% | +12.69pp | -34.3% |
| 7 | Largest Gap | Sep 1, 2025 - Mar 21, 2026 | 202 | 4 | +7.83% | -8.14% | +15.97pp | -34.7% |
All 7 approved runs. Click any row for detailed observations.
02 The Three-Gear System
The backtest has three moving parts. Remove any one and the results collapse.
Gear 1: Briefings (The Context Layer)
PreReason briefings are structured analyses of market data, processed and interpreted before the LLM ever sees them. Each briefing contains trend signals, regime classifications (labeling the market as expansion, contraction, or transition), and a rule based note on what moved with the price. The LLM receives the analysis.
The current system uses 4 modular briefings, each focused on a distinct signal domain. This architecture was introduced at Run 4. Runs 1 and 2 used 3 monolithic briefings (full-context, regime-check, market-breadth). Run 3 introduced the first modular architecture with 3 dot-namespaced briefings (btc.context, cross.regime, cross.breadth).
Sample briefings from 8 November 2025 (run 7, tick 68, simulated): the day the briefings arm stayed in cash while the price only arm bought. Click any card to see the actual briefing output.
btc.energy
Miner economics, hash rate trends, difficulty adjustments. Captures supply-side pressure that often precedes price moves by days or weeks.
cross.regime
The macro classifier. Uses SPY, QQQ, VXX, UUP, and Treasury yields to label the current environment. First signal the model reads per the weighting guide.
cross.breadth
How many assets confirm the current trend.
btc.momentum
7d/30d/90d trend signals with pre-computed mean reversion indicators. The March bottom call in Run 5 came from a momentum divergence this briefing surfaced.
Runs 1 and 2 used monolithic briefings and produced roughly 5 percentage points of delta (+5.28pp and +4.46pp). Run 3 introduced modular briefings but with 3 briefings rather than 4, and produced a similar +5.34pp. Runs 4 through 7 used the 4-briefing architecture and produced 12 to 16 percentage points of delta. The jump from ~5pp to ~15pp correlates with adding btc.energy (miner economics) and btc.momentum (trend indicators) as new data sources, not with reorganization alone. Run 3 was already modular and produced the same ~5pp as the monolithic runs, which suggests the new signal content drove the improvement.
Run 7, 8 November 2025 (simulated): the briefings arm stayed in cash; the price only arm bought.Gear 2: The Preamble (The Prompt Framework)
Every arm in every run shares the same core prompt framework. The preamble includes the current portfolio state (cash balance, open positions, unrealized P&L), the set of available actions (BUY, SELL, SHORT, COVER, HOLD), and position sizing rules. All arms share these execution constraints. The arms differ in two ways: the injected context block (briefings, price only, stale briefings, or web search results), and the strategy guidance (Treatment/Placebo get a signal weighting framework; Control/Control-WS get generic conviction-based rules).
Position & Exposure Rules
- Max single-trade size
- 80% of portfolio
- Max gross exposure
- 80% of portfolio
- Short margin
- 2.5% initial (Hyperliquid-style)
- Available actions
- BUY, SELL, SHORT, COVER, HOLD
- Temperature
- 0 (minimal randomness)
- Leverage
- None. Shorts use 2.5% margin collateral only
- Direction-flip cooldown
- 3 ticks minimum
All runs target temperature 0 to minimize output randomness. This reduces but does not eliminate non-determinism. LLM outputs can vary across API calls even with identical inputs due to batching and floating-point behavior. Temperature was explicitly recorded in Runs 6 and 7; earlier runs used the default config setting.
The prompt requires the model to reason before deciding: assess the current regime, identify primary risks, then select an action with a specific position size. This structured reasoning step makes every decision auditable and traceable.
A crucial design constraint: the preamble must stay universal. It defines the financial execution environment without encoding any personal trading strategy. A preamble too specific to the test window would overfit. The preamble sets the rules of engagement. The briefings provide the situational awareness. Keeping those concerns separate is what allows the system to generalize.
Treatment Control Placebo Control-WS Treatment receives the full signal framework, position sizing rules tied to signal counts, and 4 PreReason briefings for the current date. Verbatim from treatment.ts. Note: the prompt text uses "templates" - the term used during the runs. The product vocabulary was later renamed to "briefings." Show exact preamble textThe Control-WS Preamble: Preventing Future-Peeking
The Control-WS arm introduces a subtle but important challenge. When backtesting dates after an LLM's training cutoff, web search results could accidentally contain future information. Both 4-arm runs (Run 6 and Run 7) refined the approach: the web search query appends "before:{simulated_date}" to every query, with explicit instructions to discard forward-looking references. Per the Run 7 analysis, systemic leakage likely persists at some level. Perfect isolation is impossible when web search results are inherently uncontrolled.
Gear 3: The LLM (The Decision Engine)
Six out of the seven runs use Opus 4.6 (Anthropic). Run 2 uses Sonnet 4.5. Both models show a positive Treatment delta (+5.28pp for Opus in Run 1, +4.46pp for Sonnet in Run 2), suggesting the value comes from the context rather than the specific model. This is based on two data points (one run per model with different date windows), so it is suggestive, not confirmatory.
The critical property of both models is their training data cutoff. Every market event from September 2025 through March 2026 is genuinely novel to the model. Traditional backtesting on historical data always carries the risk that the model "remembers" past events from its training corpus. That risk does not exist here. The test window begins after the training cutoff. The Treatment arm outperforms, consistent with the hypothesis that PreReason briefings provide the context the model needs to reason about events it has zero prior knowledge of.
Controlled Variables
- Same core prompt framework across all arms
- Temperature 0 (reduces but does not eliminate LLM non-determinism)
- Identical portfolio simulator (fees, margin, position limits)
- Serial portfolio replay (each tick uses actual prior state)
- Direction-change cooldown (3 ticks, all arms)
- Agent decisions never overridden
- Same model within each run
- Same tick timing (04:00 UTC daily)
03 Infrastructure
Data Recording
Every tick in every run logs a complete record: the full reasoning text produced by the model, the chosen action and position size, portfolio state before and after execution, the BTC price at decision time, and the complete briefing content injected into the prompt.
Any decision in any run can be traced back to exactly what the model saw, what it reasoned, and what it decided. If a particular trade looks unusual, the model's reasoning and the exact context it received are both in the log.
Execution Simulation
The simulation applies a realistic fee structure: 0.045% per transaction and 0.01% funding rate per 8-hour period for short positions. Runs 1 and 2 used a higher transaction cost of 0.1% (approximately double the Hyperliquid taker fee). The fee structure was updated from Run 3 onward. Fees are applied at the same rate across all arms within a run, though the total fee impact varies by arm because arms trade at different frequencies.
There is no slippage model. Real-world slippage would reduce returns for all arms, not selectively advantage Treatment. By omitting slippage, we avoid introducing a variable that could be accused of being tuned.
Portfolio state carries forward between ticks. Positions are real within the simulation. If the model buys at tick 15, that position exists at tick 16. Unrealized gains and losses accumulate. Cash balances update. The simulation tracks a portfolio, not a series of independent bets.
Execution Pipeline
All backtest execution runs through Claude Code subagent calling, not raw Anthropic API calls. This means the system runs against subscription pricing, not custom API arrangements. A single complete backtest run (all arms across the full tick window) averages 4+ hours of processing time.
Individual tick decisions take 5 to 20 seconds. This includes the model reading the preamble, processing any injected context, reasoning through the current market state, and producing a structured action output. The backtests run at 1 tick per day, which acknowledges this limitation directly.
Concretely, each tick spawns a fresh Claude Code Agent instance. The orchestrator replays portfolio state from completed tick files on disk, assembles the corrected prompt, and passes it to a new Agent. The Agent receives only its arm-specific system prompt and a single user message. It has no conversation history, no shared memory with other ticks or arms, and no access to any prior reasoning traces. The returned agentId uniquely identifies each isolated instance. A representative invocation:
Agent
description: "Control tick 218 decision"
prompt: [system preamble + portfolio state + market data]
→ Agent reasons through context, produces JSON decision
→ Returns: agentId: a584ae1b60f2d80a6
Output logged:
{ arm: "control", tickIndex: 218, rawResponse: "{...}",
model: "claude-opus-4-6", latencyMs: 12400,
completedAt: "2026-03-14T04:00:12Z" }
This architecture makes cross-contamination structurally impossible. Each Agent is a fresh subprocess with its own context window. Treatment cannot see Control's reasoning. Tick 218 cannot see tick 217's internal state. The only information that carries forward between ticks is the portfolio state replayed deterministically from disk files. Every decision in every run can be traced to a specific agentId, the exact prompt it received, and the full reasoning it produced.
Connection to PreReason API
The briefings injected into Treatment come from the same API that serves paying customers. The MCP connection (npx -y @prereason/mcp) is the same interface available to any user. There is no special data pipeline for the backtest. Treatment receives briefings from the same API, using the same briefing IDs (btc.energy, cross.regime, cross.breadth, btc.momentum), that any subscriber can access.
If Treatment's advantage came from proprietary data unavailable to users, the results would be irrelevant to anyone considering PreReason as a product. The advantage comes from the same briefings that any user can access today.
API Activity Audit
PreReason's API activity page provides a full audit of what briefings were called, on what date, through what service (MCP or direct API), and with what success or failure codes. Every briefing request made during a backtest run is logged and visible. The Treatment arm's data inputs are independently verifiable through the API activity record.
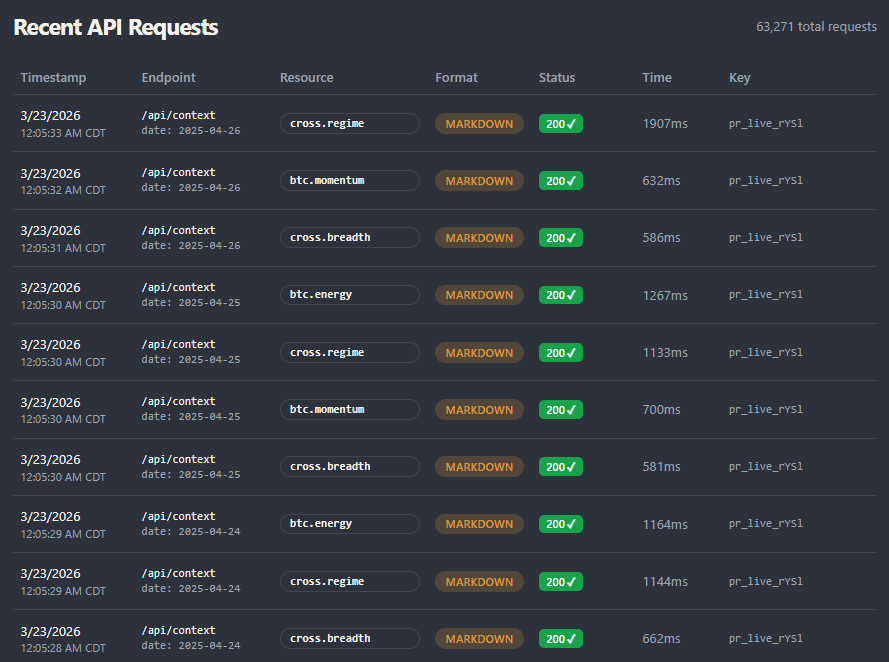
The API activity page logs every briefing request with timestamp, service type, endpoint, and response code.
API keys shown in the screenshot are truncated prefixes, not full keys.
04 What We Learned
Briefing Evolution
As described in Gear 1, the delta tripled between Run 3 and Run 4. The takeaway is that reorganizing existing data into modules was not enough. Adding new signal domains (miner economics via btc.energy, trend quantification via btc.momentum) is what moved the needle. The model needed signals it did not previously have, delivered in a format it could process.
The Placebo Effect
Placebo does not match Treatment. That is the headline finding. The Placebo arm receives real PreReason briefings, identical in format and structure, but the data is 150 to 210 days old. If structured context alone were enough, Placebo would match Treatment. It does not.
Placebo performance is highly variable across runs. In Run 2 (-6.79%) and Run 7 (-7.70%), Placebo landed near Control levels. But in Run 5, Placebo returned -18.85% against Control's -6.31%, dramatically worse. In Run 6, Placebo returned -1.55% against Control's -9.51%, dramatically better. The variance itself is informative: stale data sometimes causes confident wrong decisions, sometimes accidentally aligns with reality. Treatment's consistency across runs is the differentiator.
Web Search vs. Structured Analysis
Control-WS (present in Runs 6 and 7) receives live web search results instead of briefings. Its preamble suggests research categories -- BTC technicals, macro indicators (Fed policy, treasury yields), mining economics, cross-asset signals, and recent news -- but the model chooses its own specific queries and interprets the results without a signal framework or regime classification layer.
In practice, Control-WS surfaced information that Treatment's briefings do not include. Individual ticks showed the arm finding FOMC interest rate decisions, ETF flow data and direction, Fear and Greed index readings, and analyst commentary. Treatment's 4 briefings cover miner economics, regime classification, cross-asset breadth, and momentum. They do not cover Fed policy announcements, ETF flows, or sentiment indicators. Control-WS had a wider information set, guided by prompt suggestions that overlapped with but extended beyond Treatment's briefing scope.
The briefings arm finished 2.24 points above the web search arm in run 6, and 9.38 in run 7. In Run 6, Treatment paid $94 in fees against Control-WS's $178; in Run 7, $518 against $838. The fee difference is $84 of the run 6 gap and $320 of the run 7 gap, 0.08 and 0.32 points. In these two simulated runs, the arm with narrower but pre-analyzed information ended ahead of the arm with broader but unstructured information. Control-WS knew about the Fed. Treatment knew about hash ribbon capitulation signals. Whether a different combination of briefings -- adding Fed policy coverage, dropping one of the four, or using a single briefing instead of four -- would change this result is untested. The specific 4-briefing set was arrived at through iteration (see Briefing Evolution above), not through systematic ablation testing of all possible combinations.
What Didn't Work
The 4-briefing architecture presented here was not our first attempt at structuring context for LLMs, and the failures were more instructive than the successes.
The key failure mode was not in the briefings (Gear 1). It was in the preamble (Gear 2). Early preambles were too specific. They encoded trading strategies that happened to work during the September 2025 through March 2026 test window but would not generalize to future periods. A preamble that says "in volatile markets, reduce exposure aggressively" is encoding a strategy. A preamble that says "you may hold between 0% and 80% gross exposure" is defining a constraint. The distinction between universal priming and personal strategy was a hard-won lesson that required multiple failed runs to internalize.
Early experiments with monolithic briefings showed modest results. Some unreported experiments showed no delta or even negative delta. Briefings that included too many conflicting signals confused the model. Briefings that were too sparse left the model without enough information to make a useful decision.
The current architecture is a direct response to those earlier iterations. The 7 runs presented here emerged from a longer development process that included runs with no measurable delta, one with a negative delta, and one that was aborted after 34 ticks when aggressive shorting in the preamble produced outsized losses. Each failure narrowed the design space toward the current system.
Execution Realities
All backtest execution runs through Claude Code subagent calling. Each tick spawns a fresh subagent per arm, passes the preamble and context, waits for the JSON decision, validates it, updates portfolio state, and logs the full trace. A single tick across all four arms takes 15 to 45 seconds depending on model response time and network latency. A complete run (all arms, full tick window) averages 4+ hours of sequential processing.
The choice to run through Claude Code rather than the Anthropic API was a cost decision. A Claude Max subscription (starting at $100/month with weekly rate limits) covered the processing. Runs were spread across separate testing periods, not executed in parallel. Each run occupied its own days of iteration, with development runs, aborted attempts, and corrections consuming quota alongside the completed experiments. The equivalent API cost for this volume of processing -- including every failed run and mid-tick correction -- would have been substantially higher. Subscription pricing made it feasible to run, fail, adjust, and re-run without cost pressure influencing experimental decisions.
The backtests run at 1 tick per day (04:00 UTC). This frequency reflects both the processing overhead of LLM-based decision systems and the daily cadence of the briefing data. It is not competing with high-frequency or even intraday algorithmic trading. An agent that makes better daily allocation decisions does not need millisecond execution. The relevant comparison is "LLM with structured context vs. LLM without structured context, both operating at the same daily frequency." That is the comparison the backtests are designed to make.
05 Implications
These observations are drawn from 7 runs over a single test window. They are not proofs. But the consistency of the pattern -- positive Treatment delta across every run, two models, and market conditions ranging from -16% to -39% BTC drawdowns -- points toward three conclusions:
- The context pipeline matters more than the model. Opus 4.6 and Sonnet 4.5 both showed a positive Treatment delta with the same briefings. The context pipeline produced more delta than any prompt change we tried. In the seven simulated runs over one Bitcoin window, the briefings arm ended ahead of the price only arm in each; the briefings were revised between runs.
- Raw information access helps, but structured analysis helps more. Control-WS had live web search. It beat price-only Control by +10.45pp in Run 6. Having information helps. But Treatment beat Control-WS by another +2.24pp in Run 6 and +9.38pp in Run 7. The gap between "having data" and "having pre-analyzed context" widened during volatile periods, when the analytical framework mattered most.
- In each of the seven simulated runs, the briefings arm ended ahead of the stale briefings arm.
Open Questions
These 7 runs answer the first question (does structured context help?) but open several others that require further testing:
- Tick frequency. All runs use 1 tick per day (04:00 UTC). Would 4-hour or 1-hour ticks produce different results? Higher frequency introduces more noise, but also more opportunities for the regime classifier to add value during fast-moving markets. This is the next planned test axis.
- Model diversity. Six of seven runs use Opus 4.6. Run 2 uses Sonnet 4.5. Testing across GPT-5.4, Gemini 3.1, Llama, and other architectures would establish whether the structured context advantage is model-general or Claude-specific.
- Execution isolation. Current runs use Claude Code subagent calling within a single session. Each tick spawns a fresh Agent instance with its own context window, making cross-arm contamination structurally impossible at the call level (see Execution Pipeline above). Separate containerized LLM instances per arm would add defense-in-depth and eliminate any theoretical shared-process concern, producing an even cleaner experimental design.
- Live forward testing. All runs are backtests, even though the test window falls after the model's training cutoff. Live forward tests with real-time briefing delivery (rather than historical API calls) would validate that the effect persists outside a backtest simulation. Higher-frequency ticks become practical in a live environment where latency matters less than in sequential backtest replay.
These observations are drawn from 7 simulated runs over one Bitcoin window of 202 days, and the runs share those days. The sample size supports descriptive observations but not formal statistical inference. We report raw deltas, not p-values. The treatment effect is consistent in direction across all runs, but the magnitude varies (+4.46pp to +15.97pp). We do not claim statistical significance in the formal sense.
Explore the Evidence
This research page explains the how and why. The numbers and controls are documented separately.
See the numbers See the controls Try the briefings